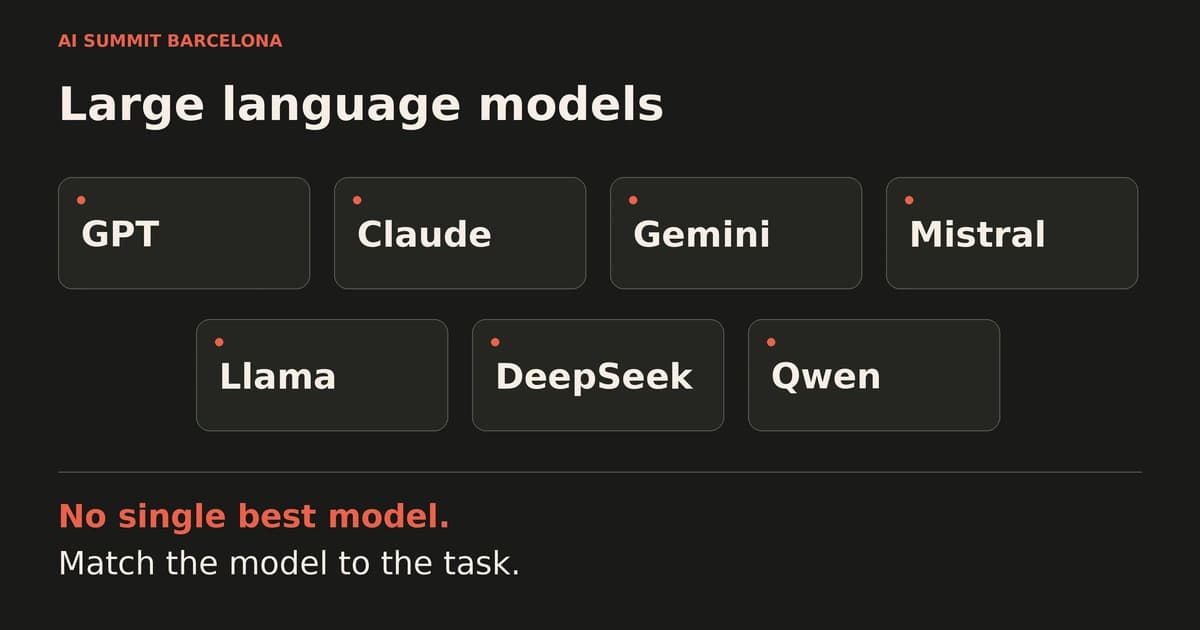
There is no single best large language model. The names people are comparing in late 2026 are GPT, Claude, Gemini, Mistral, Llama, DeepSeek and Qwen. Which one is useful depends on the task, the context window you actually need, the deployment constraint, and how you will judge the output.
This page is a comparison list, not a ranking and not a buying recommendation. Model names and capabilities move. Check the vendor page before you treat a row as current.
The model families are listed above the illustration. The sections below say how to choose among them for a company task. They do not say which model is largest, cheapest or best in the abstract.
How to choose one for a company
For the organisational decisions around a model choice, continue with the Enterprise AI guide. For Spain’s public multilingual work, read about ALIA and Salamandra.
Methodology
How to use this comparison
This is an editorial selection of model families, not a measured ranking. The official sources below establish available products and model documentation. The evaluation criteria are a framework for your own assessment.
Compare an exact model version rather than a brand. Record the date, prompt, settings, tools and scoring rules. Keep benchmark results separate from provider claims and from results measured in your own environment.
LLM comparison table
Use this table to organise a shortlist. Capabilities, context limits, prices and licences belong to the specific model version, so check its official documentation before running a comparison.
| Model family | Provider | Route to investigate | Questions for your evaluation |
|---|---|---|---|
| GPT | OpenAI | Official API catalogue | Which version supports your inputs, tools and output requirements? |
| Claude | Anthropic | Official model overview | How does it handle your documents, code and tool interactions? |
| Gemini | Official Gemini catalogue | Which input modalities and stable or preview version fit the task? | |
| Mistral | Mistral AI | Official model catalogue | Which hosted or downloadable model fits your operating constraints? |
| Llama | Meta | Official model organisation | Which weights, licence and serving configuration can you use? |
| DeepSeek | DeepSeek | Official API documentation | Which current endpoint and deployment conditions meet your requirements? |
| Qwen | Alibaba Cloud | Official Qwen model repository | Which model size, input support and licence fit your application? |
GPT (OpenAI)
The GPT family is part of OpenAI’s model catalogue. The catalogue distinguishes models by capabilities and intended tasks. A ChatGPT subscription and an API deployment are different ways of using the products; assess the one your team actually needs.
For a shortlist, check input types, supported tools and output limits for the exact model. Then measure whether it follows your instructions and produces work a reviewer can accept. Keep the cost of retries and review in the comparison.
Claude (Anthropic)
Anthropic’s model overview describes Claude versions and their capabilities. A family-level claim such as “best for coding” hides differences between versions, settings and workloads.
Test document interpretation, code changes or writing with the material you expect to use. Include incomplete information and contradictory instructions. Compare the resulting errors and review effort with the other candidates under the same conditions.
Gemini (Google)
Google’s Gemini catalogue includes models with different input and output capabilities and release states. Check whether a particular model is stable or in preview, and whether it supports the media your task requires.
For work involving images, audio or video, evaluate those inputs directly. Good performance on text questions does not establish reliable interpretation of a chart, a recording or a scanned document.
Mistral (Mistral AI)
Mistral’s catalogue includes different model sizes and access options. If European hosting or downloadable weights matter to your organisation, investigate the specific product, licence and service terms rather than inferring them from the provider’s location.
Compare a hosted option and a deployment you would operate yourself on realistic infrastructure. Include administration, monitoring and maintenance in the assessment. Read the Enterprise AI guide for the wider questions about ownership and operating a use case.
Llama (Meta)
Meta’s official Llama organisation provides model repositories and access to licence information. Downloadable weights give you deployment choices, but each model still has conditions and hardware requirements.
Evaluate the exact weights and serving setup you plan to use. Quantisation, prompts and available compute can change the result; a score reported for another configuration is not a measurement of yours.
DeepSeek
DeepSeek’s API documentation identifies its current endpoints and usage conventions. Model names, aliases and available features can change, so record the exact endpoint used in your evaluation.
Compare task quality, latency and total usage cost. Assess data handling and contractual conditions separately from model capability. A low token price does not answer those questions or establish the cost of a successfully completed task.
Qwen (Alibaba)
Qwen’s official model repository documents a family with different model configurations. Review the model card and licence for the individual release rather than treating every Qwen model as interchangeable.
For multilingual work, test the languages and terminology your users need. For a local deployment, check memory use, serving performance and the quality of the chosen configuration on your own examples.
Open vs closed models
With a managed API, a provider operates the model-serving infrastructure. With downloadable weights, you may operate a model yourself or use a hosting service. These choices change who is responsible for updates, security, capacity and support.
Open-weight does not automatically mean unrestricted use, complete training transparency or legal compliance. Managed does not automatically mean the provider’s terms fit your data requirements. Inspect the licence, hosting region, retention settings and contract for the route you would use.
The EU AI Act introduction helps identify regulatory questions. It is a starting point for governance discussions, rather than a determination that a model or deployment complies with the law.
Which LLM to choose
Write a short evaluation brief before you select a winner. It should identify the task, the people affected, the available information and the quality you need.
| Criterion | What to test | Evidence to retain |
|---|---|---|
| Task quality | Representative examples, including difficult cases | Outputs scored against the same acceptance rules |
| Factual reliability | Questions with known answers and missing evidence | Incorrect claims, unsupported citations and useful refusals |
| Context use | Your actual document lengths and formats | Missed details, retrieval failures and contradictory answers |
| Tools and actions | Required tool calls and recovery from errors | Correct arguments, permissions and handling of failed calls |
| Latency | Normal and heavier requests | Time to a usable result, including retries |
| Total cost | A completed task, including review and infrastructure | Usage charges, failure rate and reviewer time |
| Operating fit | Data, access, hosting and support requirements | Model licence, service terms and responsible owner |
Start with a small set of representative examples that you can score consistently. Keep some examples outside the prompt-development process so the comparison does not reward a setup tuned only to familiar questions. Ask reviewers to explain why they accepted or rejected an output.
Choose the simplest candidate that meets your acceptance criteria. If none does, narrow the task or change the workflow before expanding deployment. Re-evaluate when the provider changes the version or your task changes.
For a leadership discussion, bring a concrete question: which task is being considered, what evidence you have, what remains uncertain and who would own the decision. The Enterprise AI guide helps place that model choice in an adoption plan.
If the model comparison informs a leadership decision, a private AI executive briefing can help frame one model-selection question, its evaluation criteria and the evidence to gather. Technical benchmarking and deployment remain with your technical team or a separately appointed specialist.
Continue learning through Summit recordings
Check the available recordings and access conditions for perspectives relevant to your model and adoption questions.
Sources
Frequently asked questions
Which is the best large language model?
There is no universal winner. Shortlist models that meet your deployment and data requirements, then compare their outputs on representative tasks using the same instructions and scoring rules. Record the exact model version and test date.
Is Claude better than GPT?
Compare the specific versions on your own task. Coding, document analysis, writing and tool use can produce different results. Include failure cases, response time and cost rather than relying on a single leaderboard position.
What is the difference between open-weight and open-source models?
Open-weight means model weights are available to download under a licence. It does not by itself mean the training data, training code or every permitted use is open. Check the individual model licence and restrictions before choosing a deployment.
What is the best LLM for coding?
Evaluate candidates on representative changes in your own codebase, including tests, regressions and review effort. Public coding benchmarks can inform a shortlist, but they do not establish which model will perform best in your environment.
What is the best LLM for enterprise?
Start with the business task, data handling requirements and responsible owner. Compare quality, access controls, hosting, contractual terms, latency and total operating cost. A model choice is one part of the wider adoption decision.
What is a context window?
A context window is the amount of input and output a model can handle in a request, measured in tokens. A large stated limit does not guarantee accurate use of every detail. Test retrieval and reasoning at the document lengths you actually need.
Change log
- — Aligned the search title and opening with model comparisons and added a named family list before the evaluation guidance.
- — Shortened search metadata, aligned the named author and added contextual learning links; removed statistical callouts.
Written by
- Guillaume RostandCEO, AI Summit Barcelona
Guillaume leads AI Summit Barcelona. His editorial work covers AI events and the European AI ecosystem.
- Tanguy WinckerCo-founder, AI Summit Barcelona
Tanguy is a co-founder of AI Summit Barcelona. His editorial work covers company programmes, event planning and the Barcelona ecosystem.
- Adam HruskaCo-founder, AI Summit Barcelona
Adam is a co-founder of AI Summit Barcelona and contributes to its guides on AI events and the European ecosystem.
Related reading
Enterprise AI Adoption: From Awareness to Useful Experiments
A decision guide for companies moving beyond AI awareness. Diagnose the barrier, choose the appropriate format and define the evidence needed before expanding an experiment.
EU AI Act: Rules and Implementation Timeline
Read an introduction to the regulatory topics that belong in discussions about AI adoption. Use it to identify questions for the people responsible for governance and appropriate professional advice. Keep the publication context and source dates in view when assessing what applies to your organisation.
ALIA and Salamandra: Spanish AI Models
Explore ALIA and Salamandra, including BSC’s instruction-tuned checkpoints, official model cards and practical company evaluation questions.